Claude vs ChatGPT vs Gemini:2026 最新版横向实测,谁更适合你?
Data as of October 22, 2026. Prices are vendor list prices and may vary by region. 数据截至 2026 年 10 月 22 日,价格为厂商公布价,可能因地区而异。
I stopped reading launch blogs a long time ago. Benchmarks matter, but so does how a model behaves when you hand it your actual messy repository, your 500-page PDF, and your monthly budget. In October 2026 I ran the three big ones — Anthropic Claude, OpenAI ChatGPT, and Google Gemini — through the same gauntlet: real coding tasks, reasoning puzzles, long-context stress tests, API pricing math, and subscription value. Here is the no-hype, tech-nerd edition of the comparison.
我早就不看发布会通稿了。跑分重要,但更重要的,是当你把真实的一坨代码仓库、一份 500 页的 PDF、还有你每月的预算甩给模型时,它到底表现如何。2026 年 10 月,我把三家巨头——Anthropic Claude、OpenAI ChatGPT、Google Gemini——拉进同一套测试流程:真实编程任务、推理题、长上下文压力测试、API 价格账、订阅性价比。下面是去掉营销话术的技术宅版横评。
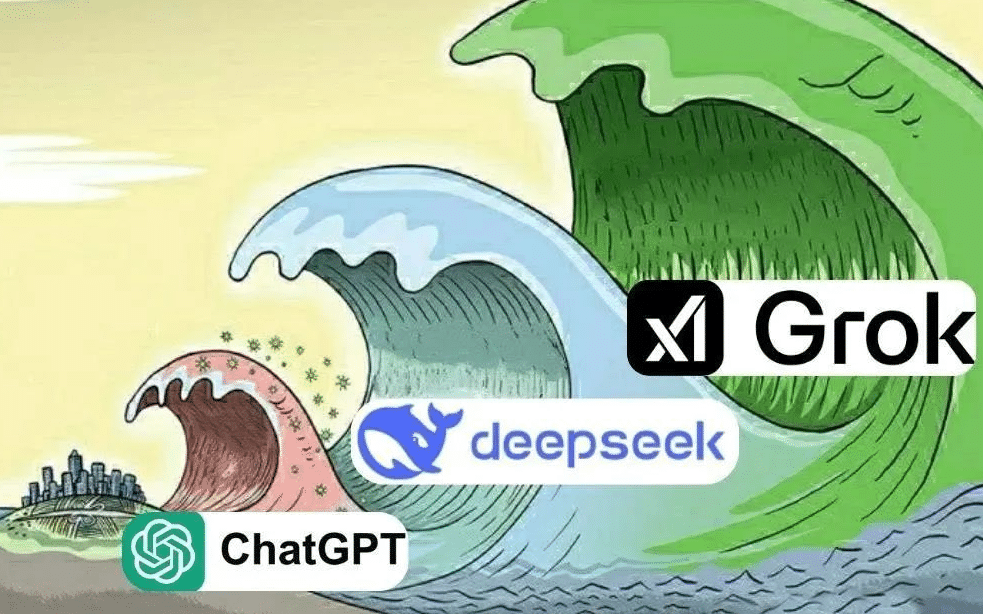
Figure 1 · The 2026 lineup, squared off. / 图 1 · 封面:2026 年三大旗舰同场对决
1. The 2026 Lineup / 选手阵容
Here is who showed up. Anthropic brings Claude Opus 5.5 (flagship, 1M-token context, 128K output, $4/$20 per million tokens), Claude Sonnet 5.5 (the workhorse, released September 28, $2/$10), and the Haiku line for cheap, fast calls (roughly $1/$5). OpenAI ships GPT-6 Astra, its new-generation model that went GA on October 20, 2026 with a 1.05M-token context and $10/$50 API pricing, alongside GPT-5.5 ($5/$30, 1M context) and GPT-5.5 Pro ($30/$180). Google counters with Gemini 4 Argon, GA since October 13, 2026 at an intro price of $2/$10, plus the broadly available Gemini 3.8 Flash at $0.75/$3.75 (intro pricing through December 31, 2026).
先看选手名单。Anthropic 带来 Claude Opus 5.5(旗舰,100 万 token 上下文,12.8 万输出,每百万 token 输入/输出 $4/$20)、Claude Sonnet 5.5(9 月 28 日发布的主力型号,$2/$10),以及面向廉价高速调用的 Haiku 系列(约 $1/$5)。OpenAI 拿出新一代模型 GPT-6 Astra,2026 年 10 月 20 日正式可用,1.05M 上下文、API 定价 $10/$50;同时还有 GPT-5.5($5/$30,1M 上下文)与 GPT-5.5 Pro($30/$180)。Google 则以 2026 年 10 月 13 日全面上线的 Gemini 4 Argon 应战,首发价 $2/$10,另有覆盖面极广的 Gemini 3.8 Flash(2026 年 12 月 31 日前首发价 $0.75/$3.75)。
Table 1 · The 2026 lineup at a glance / 表 1 · 2026 选手阵容一览
| Model / 模型 | Maker / 厂商 | Context / 上下文 | Output / 输出 | API $ in/out per MTok / API 输入/输出(美元/百万 token) | Released / 发布 |
| Claude Opus 5.5 | Anthropic | 1M | 128K | $4 / $20 | Jun 2026 |
| Claude Sonnet 5.5 | Anthropic | 1M | 128K | $2 / $10 | Sep 2026 |
| GPT-6 Astra | OpenAI | 1.05M | 128K | $10 / $50 | Oct 2026 |
| GPT-5.5 | OpenAI | 1M | — | $5 / $30 | Apr 2026 |
| Gemini 4 Argon | 1M | — | $2 / $10 (intro) | Oct 2026 | |
| Gemini 3.8 Flash | 1M | 64K | $0.75 / $3.75 (intro) | 2026 |
2. Test Setup / 测试方法
Same prompts, same repo, same clock. Every model ran the same gauntlet: (1) a real-world refactor of a 6,000-line TypeScript service with a failing integration test; (2) a hard reasoning-and-math pack; (3) QA over a 500-page technical PDF; (4) multimodal image-plus-video understanding; and (5) an agentic “fix the CI and ship it” session. All through official apps and APIs, in October 2026, from a normal dev machine. No cherry-picking, no vendor demo tasks.
同一套题、同一个仓库、同一块表。每个模型都要过五关:(1) 对一份 6000 行 TypeScript 服务做真实重构,还带一个挂掉的集成测试;(2) 一组硬核推理/数学题;(3) 一份 500 页技术 PDF 的问答;(4) 图像+视频多模态理解;(5) 一次“修好 CI 并上线”的 Agent 实战。全部走官方 App 和 API,2026 年 10 月,普通开发机。不挑题、不跑厂商演示任务。
3. Round 1 · Coding & Agents / 编程与 Agent
On the leaderboards, Claude still rules repo-level coding: Claude Opus 5.5 tops SWE-bench Pro at 89.9% (data verified October 20, 2026), and BenchLM’s October coding composite puts Claude Sonnet 5.5 first at 84.3. OpenAI’s GPT-6 Astra scores 58.2% on Terminal-Bench when driven through Codex — strong for an agent harness, though Anthropic’s flagship was not entered on that board. In my own refactor test, Claude Code and Codex both got the job done: Claude’s first-pass diff was cleaner, while Astra via Codex needed fewer retries on long multi-step runs. Gemini 4 Argon in Antigravity handled the CI-debugging loop well but was noticeably slower on long-horizon tasks. For everyday coding speed-to-quality, Sonnet 5.5 remains the best value; for autonomous agent work, Claude Code and Codex are the two you actually want.
在榜单上,Claude 依然统治仓库级编程:Claude Opus 5.5 以 89.9% 登顶 SWE-bench Pro(2026 年 10 月 20 日核验),BenchLM 10 月编程综合榜上 Claude Sonnet 5.5 以 84.3 居首。OpenAI 的 GPT-6 Astra 在 Codex 驱动下拿到 Terminal-Bench 的 58.2%——对 Agent 工程来说很强,但该榜单没有收录 Anthropic 旗舰。在我的重构实测里,Claude Code 和 Codex 都完成了任务:Claude 第一版 diff 更干净;Astra(经 Codex)在长链路多步任务上重试更少。Gemini 4 Argon 在 Antigravity 里处理 CI 排障表现不错,但长周期任务明显更慢。日常编程“速度换质量”的性价比之王仍是 Sonnet 5.5;要做自主 Agent,真正值得上手的还是 Claude Code 和 Codex。
Figure 2 · Three models, one repo. / 图 2 · 编程实测:一个仓库,三家模型
4. Round 2 · Reasoning / 推理与数学
This round was close — frontier models are now within a few points of each other. GPT-6 Astra in high-effort mode handled the math pack with the fewest wrong steps and the clearest explanations. Claude Opus 5.5’s adaptive reasoning (always on) was the most consistent on mixed puzzles: fast when simple, deep when needed. Gemini 4 Argon is explicitly tuned for “deep work” in finance, legal, and science — on a multi-step probability-plus-coding hybrid problem it matched Astra. My rule of thumb: if the problem needs relentless multi-step verification, Astra and Opus 5.5 are interchangeable at the top; Gemini 4 Argon is the dark horse for domain-heavy reasoning.
这一轮相当接近——旗舰之间的差距已经缩小到几个点以内。GPT-6 Astra 在高强度推理模式下做数学题出错最少、讲解最清楚。Claude Opus 5.5 的自适应推理(常开)在多类型混合题上最稳定:简单题秒回,难题自动加深。Gemini 4 Argon 明显为金融、法律、科学等“深度工作”调优——在一道多步概率+编程混合题上追平了 Astra。我的经验法则:需要反复多步验证的难题,Astra 和 Opus 5.5 在顶端基本平手;领域知识密集型推理,Gemini 4 Argon 是黑马。
Figure 3 · Benchmark arena: reasoning under the spotlight. / 图 3 · 跑分竞技场:聚光灯下的推理
5. Round 3 · Long Context & Multimodal / 长上下文与多模态
All three now offer roughly 1M-token windows, but they behave differently. I dumped a 500-page PDF plus a monorepo slice into each. Claude kept the cleanest recall of details from the middle of the document, and OpenAI’s own long-context evals (Graphwalks) show Claude’s previous generation already beating GPT-5.5 on 1M-token “parents” recall (72.0% vs 58.5%). Gemini is the most natively multimodal: video, audio, and images in one prompt, and with Google AI Pro the same model shows up in Search AI Mode and Workspace. GPT-6 Astra’s 1.05M window is the biggest on paper, and its knowledge cutoff (April 30, 2026) is the freshest of the three. For “upload everything and lose nothing”, I would take Claude; for “feed it video and let it reason”, Gemini wins.
三家现在都提供约 1M token 的窗口,但实际表现差别不小。我把一份 500 页 PDF 加一段 monorepo 代码分别丢进去。Claude 对文档中段细节的召回最干净;OpenAI 自家公布的 Graphwalks 长上下文评测也显示,Claude 前代在 1M token “parents” 召回上就领先 GPT-5.5(72.0% 对 58.5%)。Gemini 的多模态最原生:视频+音频+图像一条 prompt 全吃,而且 Google AI Pro 订阅下同一模型还能用在搜索 AI 模式和 Workspace 里。GPT-6 Astra 的 1.05M 窗口纸面上最大,知识截止(2026 年 4 月 30 日)三家最新。结论:“全部丢进去、一个细节都不能丢”选 Claude;“喂视频让它推理”选 Gemini。
Figure 4 · Long context: everything in, nothing lost. / 图 4 · 长上下文:全量输入,点滴不丢
6. Round 4 · API Pricing / API 价格
If you are building products, the bill matters more than the leaderboard. Per 1M tokens (input/output): Claude Opus 5.5 is $4/$20 and Sonnet 5.5 is $2/$10; GPT-6 Astra is $10/$50, GPT-5.5 is $5/$30, GPT-5.5 Pro is $30/$180; Gemini 4 Argon is $2/$10 (intro, with a planned increase from December 2026), and Gemini 3.8 Flash is $0.75/$3.75 (intro through December 31, 2026). The headline: Gemini’s Flash line is brutally cheap right now — about half of Sonnet — while GPT-6 Astra costs about 2.5x Opus. If cost-per-task is the metric, Sonnet 5.5 and Gemini 3.8 Flash are the sweet spots of 2026.
做产品的,账单比榜单重要。每百万 token(输入/输出):Claude Opus 5.5 为 $4/$20、Sonnet 5.5 为 $2/$10;GPT-6 Astra 为 $10/$50、GPT-5.5 为 $5/$30、GPT-5.5 Pro 为 $30/$180;Gemini 4 Argon 为 $2/$10(首发价,2026 年 12 月起计划上调),Gemini 3.8 Flash 为 $0.75/$3.75(2026 年 12 月 31 日前首发价)。看点:Gemini Flash 系列现在便宜得离谱——大约只有 Sonnet 的一半;而 GPT-6 Astra 大约要花 Opus 的 2.5 倍。如果按“每任务成本”算,2026 年的甜点位是 Sonnet 5.5 和 Gemini 3.8 Flash。
Table 2 · API pricing per 1M tokens (USD) / 表 2 · API 每百万 token 价格(美元)
| Model / 模型 | Input / 输入 | Output / 输出 |
| Claude Opus 5.5 | $4.00 | $20.00 |
| Claude Sonnet 5.5 | $2.00 | $10.00 |
| GPT-6 Astra | $10.00 | $50.00 |
| GPT-5.5 | $5.00 | $30.00 |
| GPT-5.5 Pro | $30.00 | $180.00 |
| Gemini 4 Argon (intro) | $2.00 | $10.00 |
| Gemini 3.8 Flash (intro) | $0.75 | $3.75 |
7. Round 5 · Subscriptions & Ecosystem / 订阅与生态
App users should think ecosystems, not just models. ChatGPT: Go at $8, Plus at $20, Pro at $100–$500 — with GPT-6 Astra reaching Work, Codex, Azure, and AWS Bedrock for enterprise. Claude: Pro at $20, Max 5x/20x at $100/$200 including API credits — Claude Code is the strongest coding agent today. Google AI: Plus at $4.99, Pro at $19.99 (5TB storage, NotebookLM Plus, 4x Gemini usage), Ultra at $99.99–$219.99 — Gemini 4 Argon now lives inside Search AI Mode, Workspace, and GitHub Copilot. My take: best everyday value is Google AI Pro (storage + AI + search in one subscription); best coding subscription is Claude Max; best general assistant is ChatGPT Plus — or Go at $8 if you are budget-conscious.
App 用户要看生态,不能只看模型。ChatGPT:Go $8、Plus $20、Pro $100–500,企业侧 GPT-6 Astra 已进入 Work、Codex、Azure 与 AWS Bedrock。Claude:Pro $20,Max 5x/20x 为 $100/$200 且带 API 额度——Claude Code 目前是最强的编程 Agent。Google AI:Plus $4.99、Pro $19.99(含 5TB 存储、NotebookLM Plus、4 倍 Gemini 用量)、Ultra $99.99–219.99——Gemini 4 Argon 已进入搜索 AI 模式、Workspace 和 GitHub Copilot。我的结论:日常综合性价比最高是 Google AI Pro(存储+AI+搜索打包);编程订阅选 Claude Max;通用助手选 ChatGPT Plus(预算紧张就上 Go,$8)。
Table 3 · Subscription plans compared / 表 3 · 订阅方案对比
| Plan / 方案 | Price (USD/mo) / 月费(美元) | Standout perks / 亮点 |
| ChatGPT Go | $8 | Budget tier, Codex included |
| ChatGPT Plus | $20 | Best general assistant value |
| ChatGPT Pro | $100–$500 | GPT-6 Pro / Astra, highest limits |
| Claude Pro | $20 | Sonnet 5.5 default, good limits |
| Claude Max 5x/20x | $100 / $200 | Best coding agent + API credits |
| Google AI Plus | $4.99 | Cheapest paid Gemini |
| Google AI Pro | $19.99 | 5TB storage + NotebookLM Plus + 4x Gemini |
| Google AI Ultra | $99.99–$219.99 | Gemini 4 Argon in app, Search, Antigravity |
8. Verdict / 结论:谁更适合你
Stop asking “which is best” and ask “which fits my week”. Here is the honest breakdown:
别再问“谁最强”,要问“谁最适合你的一周”。诚实的结论如下:
Table 4 · Who should pick what / 表 4 · 谁该选谁
| You / 你的画像 | Pick / 推荐 | Why / 理由 |
| Full-time developer / 全职开发者 | Claude (Max + Sonnet 5.5) | Best repo-level coding, strongest agent harness |
| Agent & automation builder / Agent 与自动化玩家 | ChatGPT Pro (Codex / Astra) | Long-horizon autonomy, most reliable tool loop |
| Researcher & analyst / 研究者与分析师 | Gemini (AI Pro, Argon) | Deep-work reasoning, native multimodal, Search + Workspace |
| Everyday user on a budget / 预算有限的日常用户 | ChatGPT Go / Google AI Plus | Cheap, capable, huge ecosystems |
| Team & enterprise / 团队与企业 | Match your stack: Azure→Astra, Google→Argon, security→Opus | Compliance, integration, procurement |
Figure 5 · Verdict: three paths, one choice. / 图 5 · 结论:三条路,一个选择
The gap between the three is smaller than it has ever been — and bigger than ever where it actually matters: agents, pricing, and ecosystem lock-in. Test all three on your real workload for a week. The right answer is the one that ships your week.
三家之间的差距从来没这么小——而在真正要紧的地方(Agent 能力、价格、生态绑定)又从来没这么明显。用你的真实工作流各试一周,适合你的,就是能把你的一周交付掉的那一个。
9. Sources / 参考来源
[1] Claude Opus 5.5 — Model overview, Anthropic Platform
[2] Claude Plans & Pricing, Anthropic
[3] Introducing Claude Sonnet 5, Anthropic
[4] Introducing GPT-5.5, OpenAI
[5] GPT-6 Pro in ChatGPT (GPT-6 Astra availability), OpenAI Help Center
[6] Introducing ChatGPT Go, OpenAI
[7] Introducing Gemini 4 Argon, Google
[8] Using the latest Gemini models (Gemini 3.8 Flash), Google AI Studio
[9] Gemini Developer API pricing, Google
[10] SWE-bench Pro Leaderboard, BenchLM
[11] Best LLM for Coding (October 2026), BenchLM
[12] GPT-6 vs Claude Opus 5.5 vs Gemini 3.8 (Terminal-Bench), Second Talent
[13] Gemini 4 Argon pricing tracker, AIToolTier